
User LoRA
XL
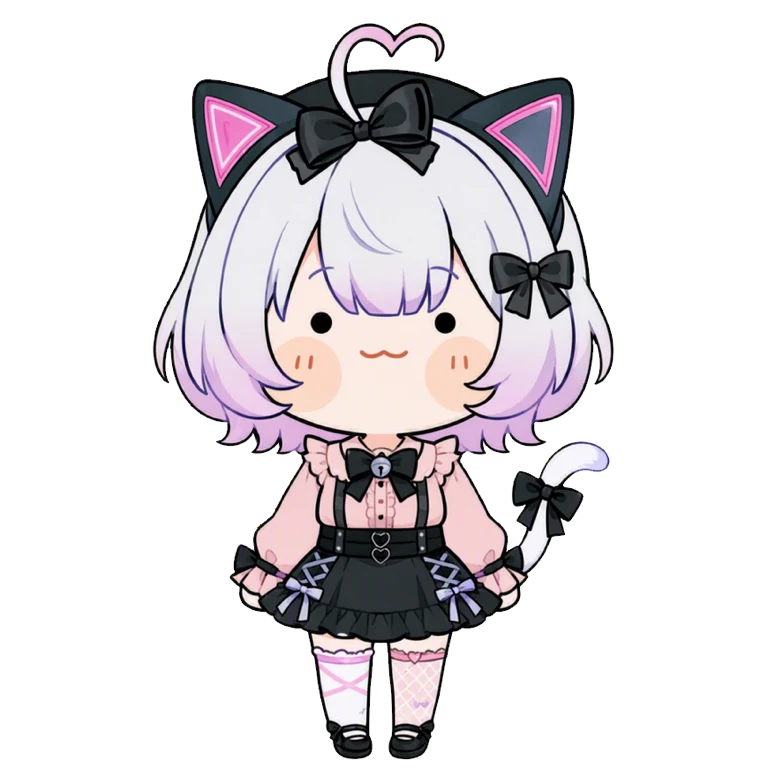

User LoRA


https://civitai.com/models/341738/bumblesteak-style-ponyxl?modelVersionId=382570
Credit the author AnyKey when posting images.
This LoRA is made for Pony XL models. I recommend using the AutismMix model.
A weight of 1.0 seems good.
This LoRA is a bit of a weird one. If you want the exact art style in the thumbnail you have to use only the tag "score_5_up" and not the default "score_9, score_8_up, score_7_up, score_6_up, score_5_up, score_4_up" tags.
(Description of LoRA on civitai page):
A colorful style with thick lines based on the artist Bumblesteak. PonyXL version of previously released NAI LoRA. [https://civitai.com/models/24459?modelVersionId=57099]
How to use No trigger word needed. Just prompt away. The dataset was mainly centered around animal and monster girls but the LoRA came out fairly versatile despite still. For more specific prompt tips please see the sample images or uploaded zip with training tags.
Misc Trained on Pony SDXL at 1024 resolution with a dataset of 77 images. All images are untouched txt2img, no inpainting or helper embeddings used for quality transparence, e.g. - things should look even better if you do. The training was done on a small subset of images, as such the output of this LoRA is not an accurate representation neither in quality or style of the source material. Go support the artist if you want the good stuff. [https://twitter.com/BumbleSteak]